IBM Sub-1nm Chip: Nanostack Architecture Packs 100 Billion Transistors
What You Will Learn
- What IBM's 0.7 nm Nanostack announcement actually demonstrates
- How stacked nanosheets change transistor density and routing
- Why 50% performance and 70% efficiency figures are projections
- What fabrication, inspection, and design steps still precede production
What IBM Announced on June 25, 2026
IBM announced sub-1 nanometer chip technology built around a new transistor architecture called nanostack. The company describes the technology as a 0.7 nm or 7 angstrom node. IBM's newsroom says the demonstration places nearly 100 billion transistors on a chip the size of a fingernail and reaches nearly twice the transistor density of IBM's 2 nm chip unveiled in 2021.
The announcement is significant because it addresses scaling beyond the node generations that dominate current semiconductor roadmaps. IBM is presenting a research result with working device demonstrations and projected performance. It is not announcing a commercial CPU, a finished AI accelerator, or a production shipment schedule.
The IBM newsroom announcement is the primary source for the headline specifications. The wording matters. Nearly 100 billion transistors, nearly twice the density, and the reported performance comparisons describe IBM's disclosed research result and its comparison basis.
What the 0.7 Nanometer Label Means
| Term | Meaning in this announcement | What it does not mean |
| 0.7 nm node | A process-generation label for IBM's research technology | Every physical feature is exactly 0.7 nm wide |
| 7 angstroms | Another way IBM describes the 0.7 nm generation | A guarantee of a specific commercial product size |
| Sub-1 nm | Logic technology below the 1 nm node label | Mass production is already available |
| Nanostack | A three-dimensional transistor architecture | A simple vertical copy of a flat nanosheet |
Process-node names have changed from direct physical measurements into labels for a generation of logic manufacturing. IBM's own research explanation says the 0.7 nm name does not correspond simply to the width of every contacted metal wire or transistor feature. This qualification prevents readers from treating the label as a ruler measurement for the whole chip.
Angstrom-level language signals the scale of the research challenge. At this size, materials, interfaces, power delivery, heat, wiring, defects, and measurement all become tightly connected. A smaller node label is useful only when the design can be fabricated, inspected, powered, and operated with acceptable yield.
How the Nanostack Architecture Works
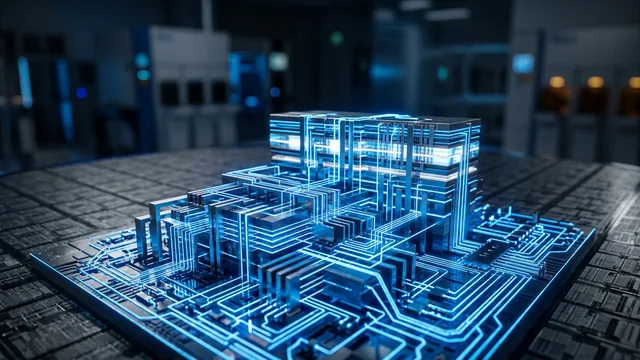
Traditional scaling mainly packs more devices into the horizontal area of a chip. IBM's nanostack design adds a vertical direction. It stacks and staggers transistor structures so more devices can occupy a similar footprint. IBM Research compares the change with building upward in a city when land is limited.
The architecture builds on nanosheet transistors. Instead of placing n-type and p-type devices only side by side, nanostack enables sequential stacking of the two types. The separation gives researchers more room to explore different channel materials and to tune each transistor type for its role.
The structure also depends on wafer-to-wafer bonding. Two wafers and their transistor layers must align closely, remain sufficiently flat, and bond through a thin dielectric layer. The electrical connections then have to cross multiple device levels without introducing unacceptable resistance, capacitance, or defects.
The IBM Research Nanostack explainer describes the architecture, wafer bonding, n-type and p-type separation, backside power delivery, and remaining manufacturing challenges.
Why Three-Dimensional Stacking Matters
The immediate benefit of vertical integration is density. IBM reports that the 7 angstrom design can roughly double the number of transistors in a given area compared with its 2 nm technology. More devices in the same footprint can support more logic, memory, or power-management capability, but density alone does not guarantee a faster chip.
Three-dimensional placement also changes the routing problem. Signals and power must reach devices at different heights. The architecture needs accurate alignment, controlled interfaces, and connections that do not erase the gain from adding more transistors. A design with high theoretical density can still be difficult to manufacture or cool.
Backside power delivery is part of IBM's approach. Moving some power-distribution work to the back of the wafer can leave more room on the front side for signal wiring. That may improve density and electrical behaviour, but it adds process steps and inspection requirements.
The TurboQuant explainer covers memory efficiency at the model and software level. Nanostack works at the device and fabrication level, so the two should not be treated as interchangeable solutions.
What IBM Has Demonstrated in the Research Device
IBM says the nanostack technology was experimentally validated through ultra-thin dielectric bonding, dual-channel engineering, and functional CMOS inverter operation with expected switching performance. These results indicate that the architecture can be physically built and can perform basic logic behaviour.
A functional inverter is an important device-level result, but it is not a complete processor. A commercial chip needs many more elements: memory, interconnects, power delivery, clocking, packaging, thermal paths, test structures, error handling, and manufacturing controls. Each layer can introduce a new failure mode.
IBM Research also describes a 40% scaling improvement in SRAM for the 7 angstrom design. The result is relevant because on-chip memory can limit how quickly an AI system feeds data to compute units. The reported SRAM result is a research metric, not a claim that every future AI processor will gain exactly 40% usable memory.
Readers should separate demonstrated device behaviour from projected system benefits. The first is measured on the research structure. The second depends on architecture, workload, software, packaging, memory hierarchy, and a manufacturing process that does not yet exist as a broad commercial platform.
Why SRAM and AI Workloads Matter
| Technology element | Potential AI relevance | Evidence limit |
| Higher transistor density | More logic or memory may fit in a given area | Does not establish system speed without a full design |
| 40% SRAM scaling | More on-chip data can reduce some memory movement | Research result does not equal workload-wide gain |
| Backside power delivery | Can free front-side routing space | Requires extra fabrication and inspection controls |
| Separate channel materials | Allows n-type and p-type devices to be tuned independently | Material gains must survive integration and yield testing |
AI workloads move large volumes of data between compute, memory, and storage. Faster arithmetic is less useful when data cannot reach the arithmetic units efficiently. More on-chip SRAM can reduce some transfers to slower memory, while a denser logic design can add compute capacity within a constrained package.
The actual result depends on the complete system. A chip designer must decide how much area goes to compute, cache, SRAM, input and output, control logic, and power management. A research-level memory scaling figure cannot be converted directly into a model-training time reduction.
This is also why hardware claims should not be read as automatic AI product announcements. IBM has demonstrated a route for future logic scaling. It has not shown a finished processor running a named production model at a specified cost or throughput.
How to Read the 50% and 70% Projections
IBM's official announcement says published technical results project up to 50% more performance or 70% greater energy efficiency compared with IBM's 2 nm node chips. These are comparative projections with a defined IBM baseline. They are not a promise that every workload will see both gains at the same time.
Performance and energy efficiency are related but different measures. A design can run faster at similar power, consume less energy at similar performance, or trade one result for the other. The final outcome depends on voltage, frequency, workload, memory access, temperature, packaging, and the software stack.
The word up to also matters. It identifies an upper result within the reported comparison, not an average across all applications. The comparison is useful for understanding the research direction, but it should not be used to forecast the performance of an unnamed commercial product.
The AI benchmark guide explains why a benchmark result needs a defined task and test setup. The same discipline applies to IBM's projected chip gains.
Why Materials and High-NA EUV Matter
At sub-1 nm generations, transistor geometry is only part of the problem. The materials that form channels, bonding layers, contacts, and wires must work together. IBM's nanostack design separates n-type and p-type devices so researchers can explore material combinations independently rather than accepting one compromise for both.
High Numerical Aperture Extreme Ultraviolet lithography is another part of the path. IBM Research says the High NA EUV equipment at Albany NanoTech is slated to be available later in 2026. The technology can print smaller and more controlled patterns, reducing the repeated processing steps that can create broken or distorted lines.
Dry resist, etch, deposition, wafer bonding, backside processing, and metrology form a connected process chain. Improving one tool does not solve the whole manufacturing problem. Each step must work with the next step at the required alignment, cleanliness, temperature, and defect level.
The Lam Research collaboration announcement describes joint work on materials, fabrication processes, and High NA EUV processes. It frames the work as development toward future logic scaling, not proof that high-volume production is already ready.
What the Lam Research Collaboration Adds
| Partner activity | Role in the scaling path | Current status in the source |
| New materials | Support channel and device performance | Joint development activity |
| Etch and deposition | Shape and build increasingly complex layers | Process-development work |
| High NA EUV | Pattern future interconnect and device layers | Process and equipment collaboration |
| Process-flow validation | Test whether the full set of steps works together | Aim of the five-year agreement |
Lam Research says the IBM collaboration is a five-year agreement focused on materials, advanced etch and deposition capabilities, and High NA EUV lithography. The companies intend to develop and validate full process flows for nanosheet and nanostack devices, including backside power delivery.
A collaboration of this kind is evidence of an ecosystem effort. It does not mean that all tools, materials, design rules, or yield targets have been solved. The route from a research wafer to a commercial logic node requires repeated learning cycles and capital-intensive process qualification.
For readers tracking the semiconductor supply chain, the relevant question is whether these partnerships produce reproducible process flows and acceptable yield. A press release can establish the scope of collaboration. Later technical papers, equipment availability, foundry announcements, and product results are needed to assess commercial progress.
What Still Stands Between Prototype and Production
| Production requirement | Why it matters | IBM Research status described |
| Wafer bonding | Layers must align and remain electrically reliable | New bonding approach demonstrated in research |
| Thermal management | Dense devices create difficult heat paths | Thermally conductive bonding remains an area of work |
| Inspection and metrology | Defects must be detected at three-dimensional interfaces | 3D inspection is listed among needed capabilities |
| Design automation | Engineers need tools for new 3D layouts and checks | EDA compatibility remains a development need |
| Yield and reliability | Large wafers must produce enough usable devices | High-yield production is a future objective |
IBM Research identifies several remaining requirements, including thermally conductive dielectric bonding, improved backside and bevel processing, three-dimensional metrology and inspection, and electronic-design automation compatible with 3D designs. These details are important because they show where the engineering work continues.
Production also requires a stable supply chain, repeatable process recipes, packaging capacity, customer design kits, and testing infrastructure. A device can function in a laboratory while still being too expensive, too variable, or too difficult to integrate into a full product.
The assigned IBM technology page is now framed around those evidence limits rather than around a near-term product launch. The distinction protects readers from confusing an important research step with a market-ready chip.
How to Evaluate the Broader Chip Implications
The IBM result suggests that Moore's Law-style scaling can continue through architectural changes even as traditional two-dimensional shrinking becomes harder. IBM Research projects that nanostack could extend logic scaling for at least a decade and describes a roadmap toward 2040. Those statements are a research roadmap, not a guaranteed industry timetable.
For AI systems, the potential value is a combination of compute density, memory access, power efficiency, and packaging. The same architecture could also matter for cloud infrastructure, mobile devices, and other systems that need more capability within a limited power or physical budget.
Competitors and suppliers will determine how much of the concept spreads. A research node becomes strategically important only when designers can use it, manufacturers can build it repeatedly, and customers can pay for the resulting performance. The comparison with 2 nm is a useful technical baseline, but it does not by itself show commercial advantage.
Readers can compare this hardware development with the AI voice-agent architecture guide and the offline AI models guide. Those topics show how compute constraints appear at the software and device level, while Nanostack addresses the underlying logic technology.
Conclusion: A Research Milestone With a Long Production Path
IBM's sub-1 nm announcement describes a 0.7 nm or 7 angstrom logic technology using a three-dimensional nanostack architecture. IBM reports nearly 100 billion transistors on a fingernail-sized chip, nearly twice the density of its 2 nm node, and projected gains of up to 50% in performance or 70% in energy efficiency against that baseline.
The strongest verified claim is that IBM has demonstrated a physically built device architecture with functional CMOS behaviour, wafer bonding, dual-channel engineering, and SRAM scaling results. The larger AI and commercial benefits remain dependent on full-chip design, packaging, process control, yield, inspection, and software.
Nanostack therefore matters as a possible route beyond flat scaling, not as a processor that consumers can buy today. The next evidence will come from reproducible process flows, design automation, High NA EUV readiness, manufacturing yield, and product-level benchmarks. Until those arrive, readers should treat the announcement as a research milestone with a demanding production path.
Frequently Asked Questions

SK Jabedul Haque
Building India's most trusted finance education platform — simplifying news, schemes and market trends so anyone can understand and invest confidently.
Read full bio
Never miss an update
Get our clearest explainers on schemes, markets and money — read what matters, without the noise.
Explore more articles