How Small Businesses Measure Real ROI from AI Agents in 2026
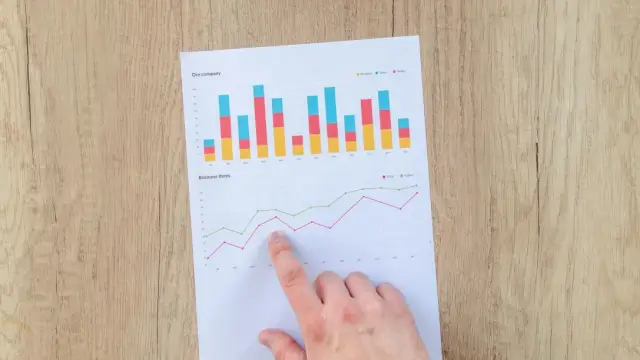
AI Agent ROI for Small Businesses 2026 is not a case for buying an agent first and finding a benefit later. A useful ROI review begins with one defined process, a clear before state, a named owner, and an outcome that can be checked. The agent may reduce manual work, improve response quality, increase capacity, or create a service that was not practical before.
Microsoft guidance recommends defining value before building, capturing telemetry from day one, and reviewing results with a named sponsor. IBM guidance similarly recommends a narrow use case, a baseline, cost focused deployment, and measures that connect speed to outcome, cost to serve, and new capability.
The right question is not whether an agent sounds intelligent. It is whether the business can show what changed, what it cost, what review work remains, and whether the change is safe to scale. A small operator can answer those questions with a simple worksheet and a consistent measurement window.
For context, compare this guide with our no-code AI agent builder guide, our vertical and horizontal agent guide, and our AI security guide.
What You'll Learn
- How to define an AI agent use case before building it.
- How to create a baseline for time, cost, quality, and capacity.
- How to separate hard financial value from soft operational value.
- How to run a practical ROI review without inventing a benchmark.
Why Does AI Agent ROI Measurement Break?
ROI measurement breaks when a business starts with a tool rather than a process. A general claim such as faster work does not identify which task became faster, how often it runs, whether quality changed, or whether someone must correct the result. Without those details, a dashboard can show activity but not business value.
A second problem is the missing baseline. If the owner never records the old handling time, error rate, backlog, or cost per completed outcome, the post launch number has no reliable comparison. A demonstration can look impressive while the real process remains unchanged.
IBM reports that only about 29 percent of executives in a cited Think Circle discussion said they could measure AI ROI confidently, while 79 percent saw productivity gains. The figures are a warning about measurement discipline, not a benchmark for every small business. Productivity is not automatically profit.
A third problem is incomplete cost accounting. Model usage is only one line. Include subscriptions, connectors, hosting, setup, monitoring, review time, correction time, security work, failed runs, and migration work. If the agent creates new demand for human checking, that effort belongs in the total cost.
What Should a Small Business Measure First?
Start with one workflow that has a clear trigger and a reviewable output. Suitable examples include classifying inbound enquiries, extracting fields from documents, preparing a first response, routing support requests, creating a content brief, checking a list against rules, or summarising a meeting for human approval.
Pick a process that happens often enough to produce evidence during the pilot. It should have a named owner, a defined start and end, accessible records, and a manual fallback. Do not begin with a workflow that can spend money, change legal terms, delete records, or contact every customer without approval.
Define the outcome in plain language. For a support workflow, the outcome might be a correctly routed ticket with a suggested reply. For invoice processing, it might be a structured record ready for approval. For content work, it might be an edited brief that meets a checklist.
| Question | Example answer | Evidence to capture |
|---|---|---|
| What starts the workflow? | A form, email, document, or record change | Time and source of each input |
| What is the final outcome? | A routed ticket, draft reply, or approved record | Completed outcome and reviewer decision |
| Who owns the result? | A support lead, operator, or finance reviewer | Named owner and escalation path |
| What can go wrong? | Missing data, duplicate input, bad tool response, or unsafe request | Error, correction, and recovery action |
Our guide to building AI agents without coding provides related context on choosing the workflow boundary before selecting a tool.
How Do You Build a Reliable ROI Baseline?
Measure the existing process before deployment. Record a sample of completed outcomes during a fixed period that represents normal work. The sample does not need to be perfect, but it should include ordinary cases, slow cases, incomplete inputs, and cases that require escalation.
For each outcome, record elapsed handling time, active human minutes, direct cost, quality result, rework, and completion status. Separate waiting time from active work. An agent may shorten active work while leaving a queue or approval delay unchanged.
Use the same definitions after launch. If pre launch time means active handling minutes but post launch time means total elapsed time, the comparison is not meaningful. Record the source system, measurement owner, period, and any exclusions in the worksheet.
A small business can use a one week baseline for a frequent process or a longer period for seasonal work. The correct window is long enough to capture normal variation and short enough to support a clear decision. Do not extend the baseline simply to obtain a favourable result.
Which Metrics Show Operational Value?
Operational metrics show whether the workflow is behaving differently. Track completed outcomes, active minutes, elapsed time, queue age, first response time, rework, error rate, approval rate, escalation rate, and quality review results. These measures help explain why financial value did or did not appear.
Use a small set of leading and lagging indicators. Usage, completion, and approval are leading signals that the workflow is being used. Cost per outcome, customer retention, revenue, or avoided expense are lagging signals that connect the workflow to business results.
Do not celebrate volume alone. More automated runs can mean more useful capacity, or it can mean repeated failures. Pair each usage measure with quality and exception measures.
| Metric | Calculation | What it explains |
|---|---|---|
| Active time per outcome | Total human handling minutes divided by completed outcomes | Whether the process uses less direct effort |
| Cost per outcome | Total process cost divided by completed outcomes | Whether service delivery became cheaper |
| Quality rate | Accepted outcomes divided by reviewed outcomes | Whether speed came with an accuracy cost |
| Exception rate | Escalated or failed cases divided by all cases | How much work still needs specialist handling |
| Capacity released | Baseline active minutes minus post launch active minutes | How much time can be reassigned or absorbed |
What Is the Correct AI Agent ROI Formula?
A practical formula is: ROI equals the value created minus the total cost, divided by the total cost, multiplied by 100. Value created can include verified cost savings, contribution from additional revenue, or a separately reported capacity benefit. Do not place unverified optimism inside the numerator.
Total cost should include the agent plan, model usage, integrations, hosting, implementation, monitoring, training, human review, corrections, and a fair share of security and administration. If a cost is one time, show it separately from recurring operating cost so the payback period is not hidden.
For example, suppose an owner estimates verified annual savings of 12,000 dollars and additional contribution of 3,000 dollars. Suppose total first year cost is 5,000 dollars. The illustrative ROI is 200 percent. This is a worked example, not a market benchmark and not a promise that another business will produce the same result.
When revenue is included, use contribution rather than gross sales when possible. Faster output may not create profit if delivery cost, refunds, review, or customer acquisition cost rises. If the causal link is uncertain, report revenue influence as a separate scenario instead of presenting it as realized ROI.
| Value or cost line | Measurement method | Reporting caution |
|---|---|---|
| Time savings | Baseline active minutes minus post launch active minutes | Do not count unused capacity as cash savings without a business decision |
| Cost to serve | Total process cost divided by completed outcomes | Include human review and correction time |
| Revenue contribution | Incremental contribution linked to the workflow | Separate correlation from verified causation |
| Risk or quality value | Change in errors, escalations, or avoided rework | Use a documented cost or report it as a non financial benefit |
How Do You Measure Time Saved Without Overclaiming?
Time saved is often the first useful signal for a small business, but it needs a careful definition. Measure active human minutes before and after the agent. Then ask what happened to the released capacity. It may support more customers, faster delivery, better review, or simply reduce overload.
Do not convert every saved minute into payroll savings. A business may keep the same staff and use the time for quality, sales, product work, or recovery from peak demand. Those outcomes can be valuable, but label them as capacity value unless a real expense is removed.
Track correction minutes as well as creation minutes. If an agent drafts an answer in one minute but requires six minutes of checking and rewriting, the net time may be higher than the old process. Record median and high case results when a few difficult cases materially affect the workload.
For a related view of coding and review boundaries, read our coding agent comparison.
How Do Hard and Soft ROI Differ?
Hard ROI is tied to measurable financial outcomes such as lower cost, higher contribution, reduced paid service volume, or an expense that the business actually avoids. These figures should be connected to accounting records, time records, or a repeatable operational calculation.
Soft ROI includes employee satisfaction, customer experience, decision quality, reduced stress, better access to information, and improved resilience of a process. IBM identifies such measures as relevant to AI value while noting that they are less direct in the short term.
Soft value should not be dismissed, and it should not be inflated into hard savings. Use a short survey, quality score, response-time measure, or retention signal where appropriate. Report the result beside the financial calculation with a clear label.
| Value class | Example measure | How to report it |
|---|---|---|
| Hard financial | Cost per completed outcome or verified contribution | Show source, period, and calculation |
| Operational | Active minutes, queue age, or error rate | Compare the same baseline definition |
| Customer | Response time, satisfaction, or repeat contact | Separate agent effect from other service changes |
| Employee | Review burden, confidence, or task satisfaction | Use a survey or documented review method |
What Do Benchmarks and Surveys Really Tell You?
Benchmarks can provide context, but they are not a substitute for a business baseline. Results vary with task volume, data quality, labour cost, model choice, workflow design, approval rules, and how a study defines success.
IBM cites a 2025 CEO study in which around 25 percent of AI initiatives delivered expected ROI and 16 percent scaled enterprise-wide. Those figures describe a broad study context. They do not establish a target for a local shop, agency, clinic, or solo consultancy.
IBM also reports that product development teams following four AI practices to an extremely significant extent reported median generative AI ROI of 55 percent. That is an industry-specific result. Treat it as evidence that implementation practice matters, not as a guaranteed return.
Microsoft provides a different type of reference. Its guidance focuses on three stakeholder questions: whether agents are used, whether they work well for the people they serve, and whether they return enough value to justify scaling. This structure is often more useful than copying a headline percentage.
Our AI cybersecurity guide explains why quality, security, and risk measures belong beside financial metrics when an agent can access business systems.
How Should You Account for Total Cost?
List costs in the same period as benefits. Recurring costs may include subscriptions, model calls, storage, connectors, messaging, hosting, support, and monitoring. Variable costs may rise with volume, long prompts, tool calls, retries, or human approval.
One time costs may include process mapping, prompt and workflow design, data cleanup, integration, testing, staff training, legal review, and migration planning. If the owner performs the work without an invoice, record the hours and assign a reasonable internal rate for decision making.
Include failure cost. A wrong classification, duplicate action, leaked record, missed escalation, or service interruption can erase apparent savings. A small pilot should define the maximum acceptable error and the action taken when it is exceeded.
Review portability and vendor dependence. A low starting price does not prove low total cost if the workflow cannot be exported, audited, or moved when the product changes. Our agent runtime comparison provides related context on control boundaries.
How Can a Small Business Run an ROI Pilot?
Use a bounded pilot with one workflow, one owner, one measurement sheet, and a fixed review date. Keep the first action reversible. Start in shadow mode when possible, where the agent prepares a result while a person continues to make the final decision.
Define a success rule before launch. It might require lower active minutes without a quality decline, a lower cost to serve at the same service level, or a higher completion rate with acceptable review. Define a stop rule for safety, error, cost, or customer harm.
Compare like with like. Use the same case mix where possible, record excluded cases, and note other changes such as staffing, pricing, seasonality, new software, or a marketing campaign. A simple before and after comparison is useful when its limits are visible.
At the review date, decide whether to stop, redesign, continue as a controlled pilot, or scale. Scaling should require evidence that the process is maintainable, not only that the demonstration looked good.
| Pilot stage | Owner action | Decision evidence |
|---|---|---|
| Define | Write the outcome, baseline, guardrails, and stop rule | Approved measurement sheet |
| Observe | Run shadow or human approved cases | Quality, time, cost, and exception records |
| Compare | Review the same definitions against the baseline | Net value and unresolved risks |
| Decide | Stop, redesign, continue, or scale | Named decision maker and next review date |
What Mistakes Should You Avoid?
Do not measure only the number of runs. Usage can rise while outcomes worsen. Pair usage with completion, approval, quality, correction, and exception measures.
Do not call capacity a saving before deciding how the capacity will be used. A saved hour can support revenue, reduce overload, improve quality, or remain unused. Each outcome has a different financial interpretation.
Do not hide implementation and review cost. If the owner spends evenings correcting output, the cost is real even when no invoice appears. Record the time and show it separately if the estimate is uncertain.
Do not use an external benchmark as a promise. A survey can have a different sample, period, task mix, and definition from your business. Use published figures for context and your own records for the decision.
Do not ignore security and product lifecycle. An agent that produces a fast answer but exposes private data or depends on a discontinued service has negative business value. Our service status guide shows why availability and fallback planning also matter.
Conclusion: What Is Real AI Agent ROI?
Real AI agent ROI is a traceable relationship between a defined workflow, a before state, a measured change, and the full cost of producing that change. Small businesses do not need a large analytics department to start. They need a narrow use case, consistent definitions, a named owner, representative cases, and the discipline to count review and failure work.
Begin with cost and time where the evidence is clearest. Add quality, customer, employee, and new capability measures as the pilot matures. Report hard financial value and soft operational value separately. Treat external survey percentages as context rather than a promise.
Microsoft and IBM both point toward the same practical lesson: define value before building, establish a baseline, measure use and outcome, account for cost, and scale only when the process is useful and governable. That is how a small business turns an AI agent experiment into a decision it can defend.
Frequently Asked Questions

SK Jabedul Haque
Building India's most trusted finance education platform — simplifying news, schemes and market trends so anyone can understand and invest confidently.
Read full bio
Never miss an update
Get our clearest explainers on schemes, markets and money — read what matters, without the noise.
Explore more articles